Cheng He · 贺铖

M.S. Student at Fuzhou University · Applying for Fall 2027 PhD programs

My research spans multimodal learning, reliable AI, and medical AI. I study VLMs, cross-modal alignment, visual-language grounding, and evidence reasoning; domain generalization, distribution shifts, test-time adaptation (TTA), and robustness; and computational pathology, medical imaging, fine-grained cell analysis, and medical multimodal learning. I also follow frontier developments in AI, including VLA models, world models, and 3D reconstruction.

Multimodal LearningReliable AI & GeneralizationMedical AIAI Frontiers: VLA · World Models · 3D Reconstruction
Research

Three questions guiding my research

01

Computational Pathology & Fine-grained Visual Analysis

How can we extract meaningful fine-grained evidence and model structured visual representations?

I study cell detection and representation learning in computational pathology, including cervical cytology and whole-slide image analysis.
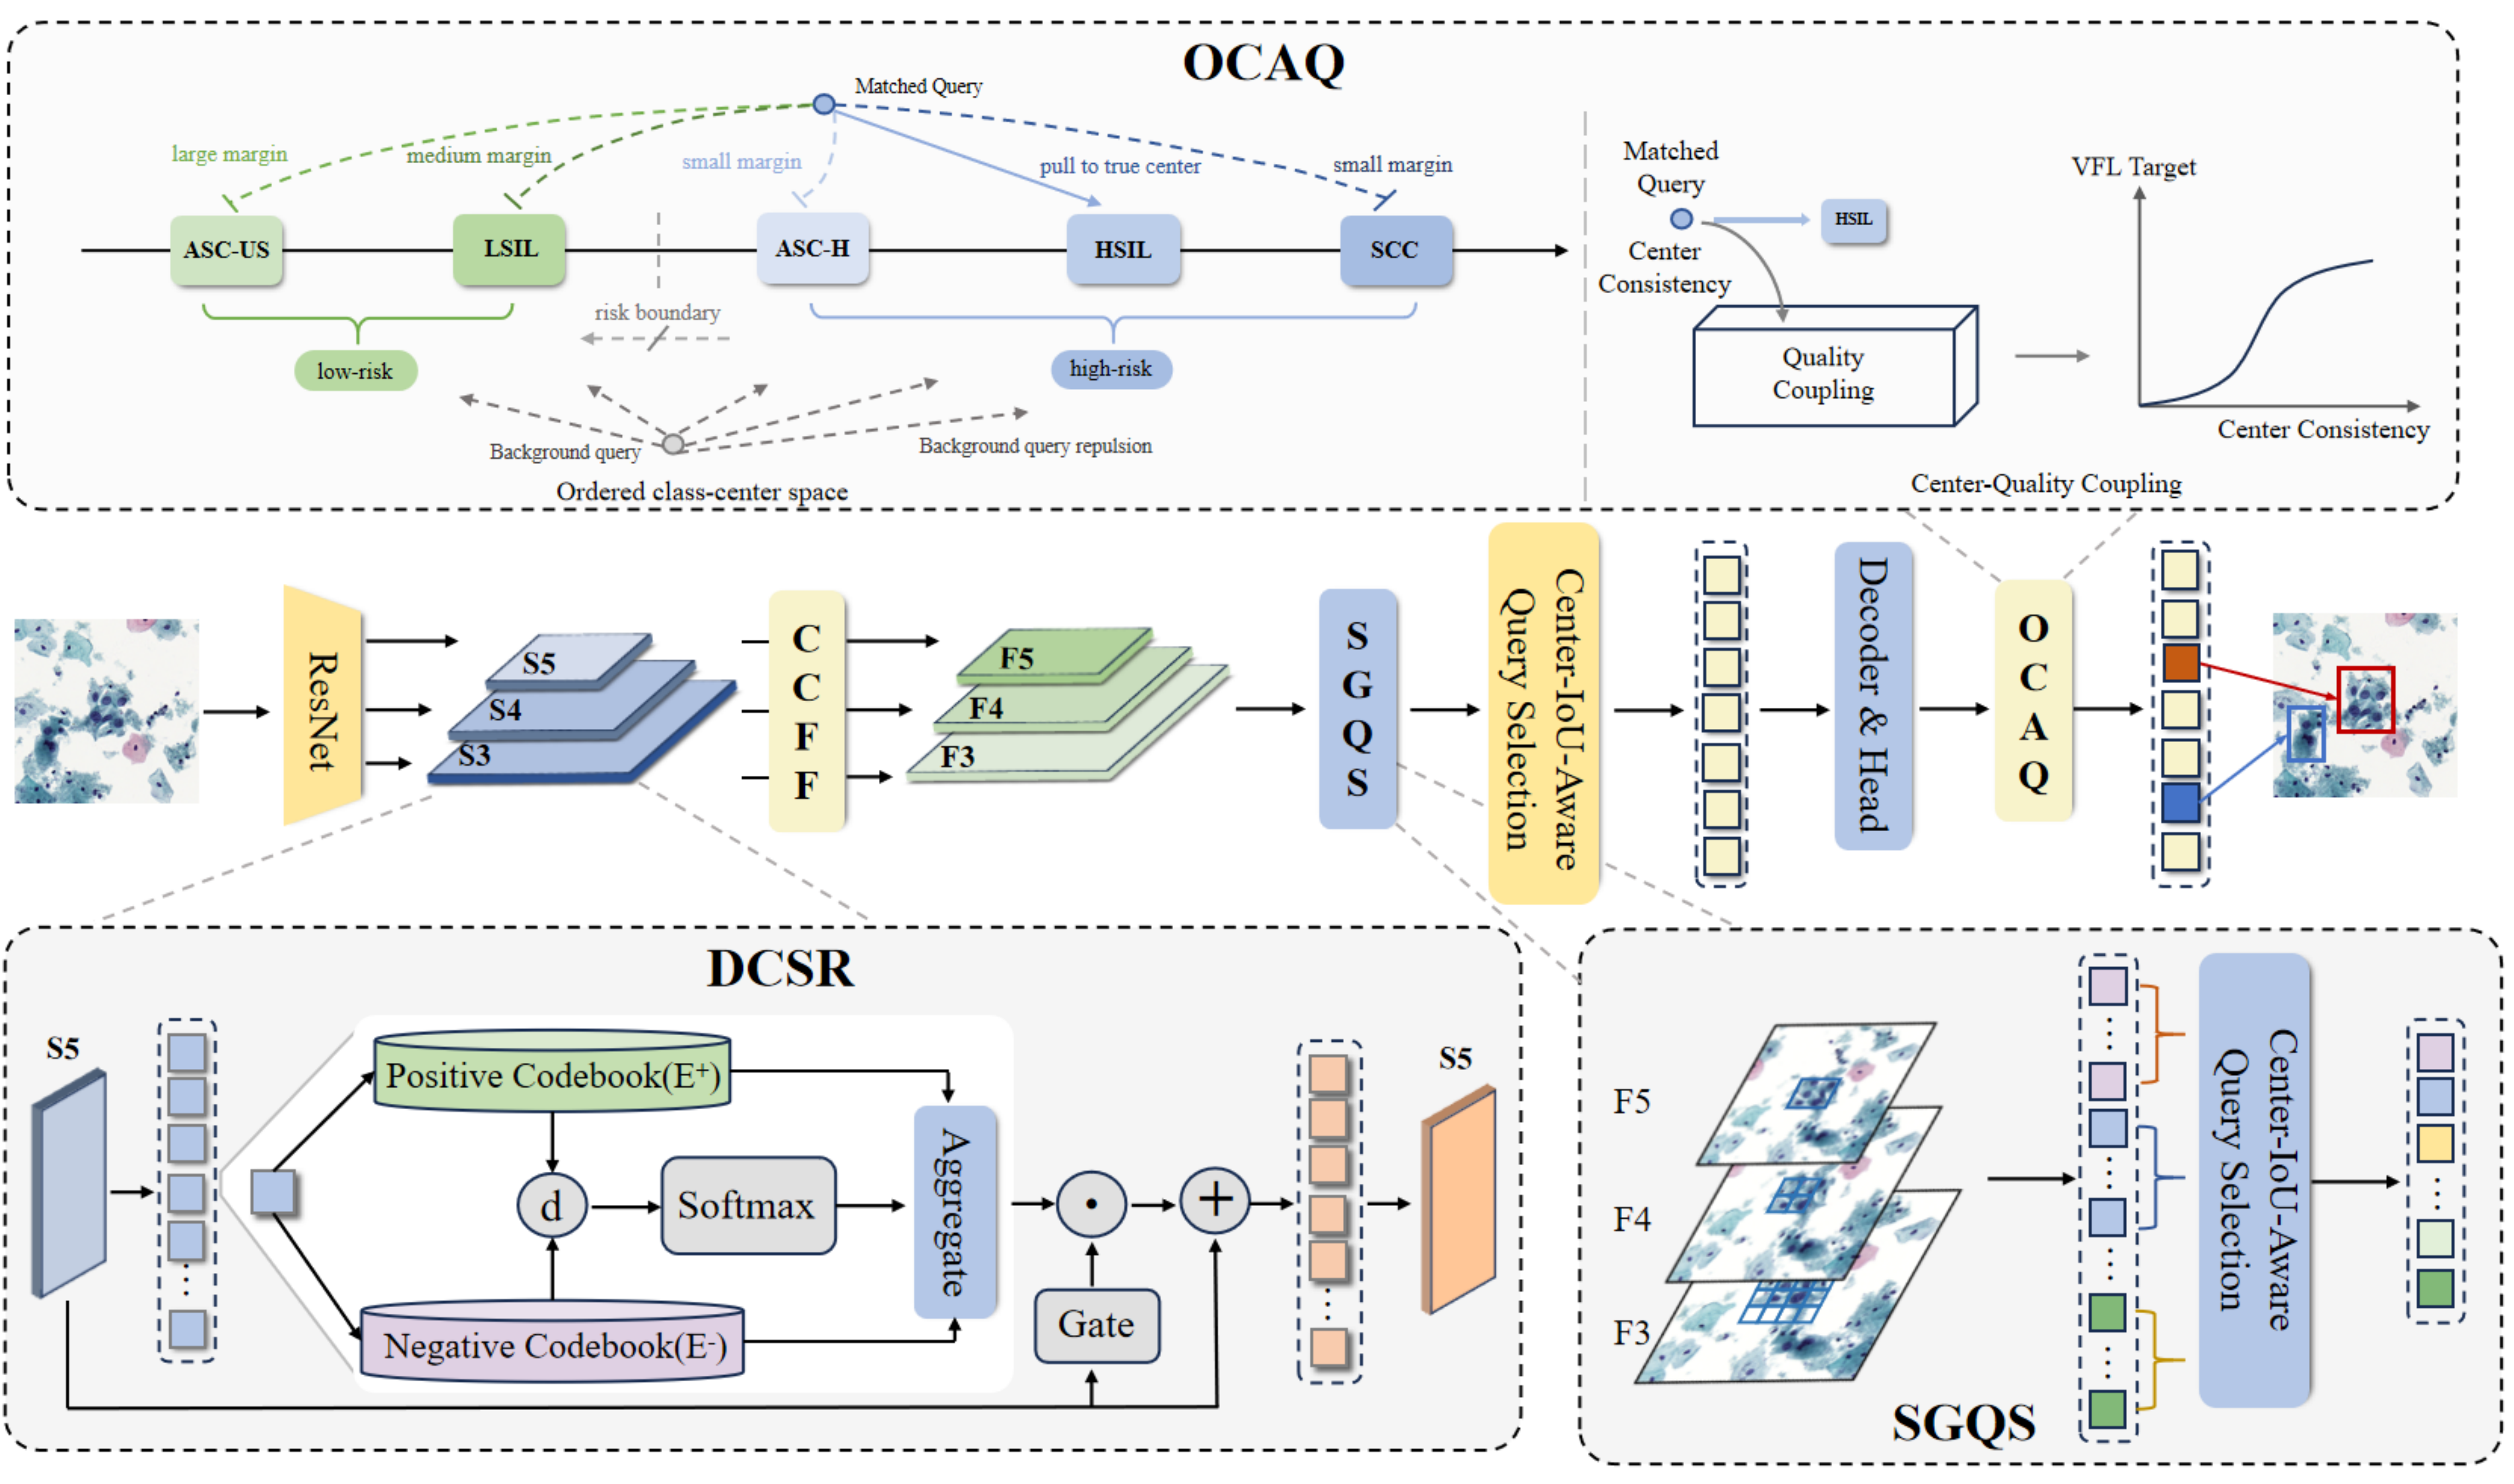
Object detectionStructured representationsWhole-slide images
02

Weakly Supervised & Multimodal Visual Learning

How can we learn from limited annotations and reason with multimodal information of varying reliability?

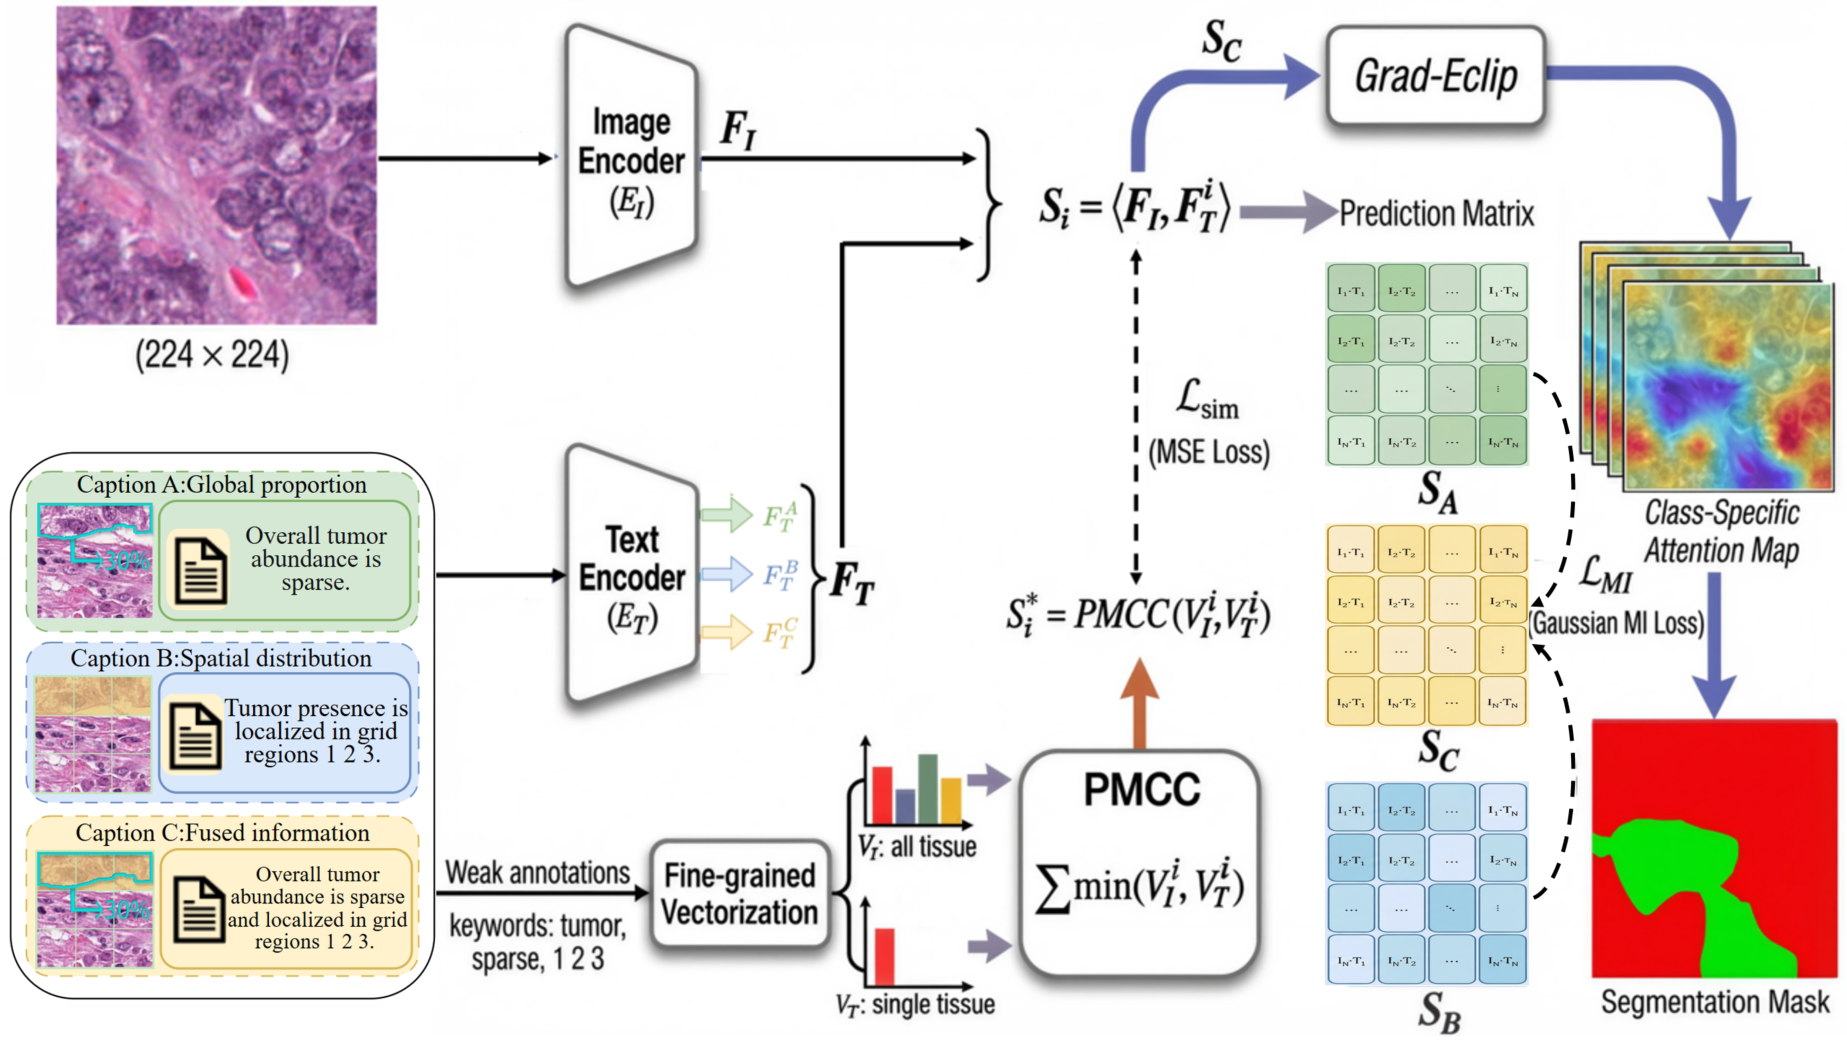
My work explores text-guided weak supervision, vision-language alignment, and reliable use of visual and linguistic evidence.

Weak supervisionVision-language alignmentMultimodal reliability
03

Domain Generalization & Robust Representation Learning

How can learned representations remain reliable under distribution shifts?

I investigate single-source domain generalization, using cross-scanner and cross-dataset medical object detection to study robustness beyond the training distribution.

Domain generalizationRobust representationsDistribution shifts
Publications

Selected First-Author Research

Manuscript under Review

Single-Source Domain Generalization

First Author · Manuscript under Review

We study single-source domain generalization for medical object detection, focusing on instance-level response heterogeneity under distribution shifts. The method improves robustness across scanners and datasets without additional inference-time computation.

Manuscript under Review

Multimodal Reliability Learning

First Author · Manuscript under Review

We study multimodal reliability in vision-language models, focusing on the effective use of visual and linguistic information in complex scenes and under distribution shifts. This work aims to improve vision-language understanding, generalization, and prediction reliability.

Collaborative Publications

PRCV 2026Accepted

Reliability-Aware Counterfactual Fusion for Debiased Multimodal Sentiment Analysis

Chinese Conference on Pattern Recognition and Computer VisionCCF-C · Fourth Author

CRAFT estimates sample-level text reliability through cross-modal consistency and uses a counterfactual branch to reduce unreliable language influence, mitigating language-dominated prediction bias and improving multimodal fusion robustness.

PRCV 2026Accepted

DT-VG: Multi-Segment Text-Guided Drone Trajectory Visual Grounding

Chinese Conference on Pattern Recognition and Computer VisionCCF-C · Fourth Author

DT-VG combines hierarchical text encoding with physics-aware structural constraints to capture multi-segment semantic dependencies and motion consistency, predicting continuous and geometrically precise trajectories from a single static drone image.

TMMUnder Review

Image-Grounded Morphology Steering for Cervical Cytology Cell Detection

IEEE Transactions on MultimediaCCF-A · Sixth Author

Image-grounded morphology steering uses frozen text prototypes for semantic compatibility and bounded residuals at the final decoder layer to strengthen diagnostic morphology evidence, improving fine-grained discrimination and cross-domain localization in deformable detectors.

Research Interests

Research Interests & Exploration

During my master’s studies, I have investigated fine-grained visual perception, weakly supervised and multimodal learning, and domain generalization, gaining experience in algorithm design, model implementation, experimental validation, and scientific writing.

Beyond my current work, I am interested in how vision-language-action models (VLA), world models, and 3D reconstruction connect spatial perception, reasoning, and action, and what research questions arise at these intersections.

Building on my research experience, I hope to explore questions with scientific and practical value while remaining open to cross-disciplinary research and academic exchange.

Projects

Research in practice

Fujian Provincial Health Commission · Science and Technology Program

Cervical Glandular Lesion Cell Recognition via Multimodal Data Fusion

2024 – 2026
Technical Lead (Visual Screening)Cervical CytologyTCT WSI Screening
The problem

Cervical cytology slides lack the relatively stable spatial structure and contextual information found in histopathology, while abnormal cells are sparse, morphological differences are subtle, and whole-slide images are extremely large. The core challenge in automated TCT screening is to identify diagnostically meaningful abnormal cells within vast numbers of normal cells and complex backgrounds, then form a reliable slide-level screening result.

My contribution

I lead the visual screening pipeline from TCT WSI processing and cell detection to abnormal-cell evidence aggregation, slide-level prediction, and evaluation, including experimental dataset construction, model training, result analysis, and screening-threshold selection.

Project outcomes

In internal validation, the model achieved approximately 50% specificity at a high-recall operating point of 95% sensitivity, enabling effective triage of many negative slides while prioritizing the detection of abnormal cases. In a screening setting with an abnormal-case prevalence of about 10%, this corresponds to an estimated 45% of all slides entering a low-risk queue, shifting manual review from exhaustive screening toward prioritized review of high-risk cases and key cells.

95%Sensitivity
50%Specificity
≈45%Potential Low-risk Triage
Potential Screening Utility

The project establishes a complete analytical pathway from ultra-high-resolution WSI to cell-level evidence and then to slide-level screening results. This workflow may reduce repetitive review of negative slides in large-scale cervical cytology screening and direct limited human review capacity toward high-risk cases and diagnostically important regions.

About

Education & background

I am a master’s student in Computer Technology at Fuzhou University. My interests span multimodal learning, reliable AI, and medical AI, with prior work in computational pathology. I also follow frontier developments in AI, including VLA, world models, and 3D reconstruction.

Education

Fuzhou UniversityProfessional Master’s in Computer Technology

School of Computer and Data Science · GPA: 3.4 / 4.0

Class Representative, Class 4, Computer Technology Program

Yuzhang Normal UniversityUndergraduate study in Data Science and Big Data Technology

Ranked 2nd in comprehensive evaluation in the major.

Technical Skills

Research & Engineering

Medical Imaging & WSI Processing

OpenSlideOpenCVWSI Processing

Experienced in whole-slide image processing, patch construction, and pathology data organization, supporting both cell-level analysis and WSI-level research workflows.

Deep Learning & Model Engineering

PythonPyTorchCUDAONNXTensorRT

Able to independently implement, train, debug, and evaluate computer vision models, with experience in ONNX export and TensorRT inference optimization and an emphasis on reproducible experimentation.

Linux & Research Computing Infrastructure

LinuxGPU ServersCUDASystem Administration

Since the laboratory’s early days, I have deployed Linux/GPU servers and set up research computing environments. I independently maintain NVIDIA drivers, CUDA and deep learning environments, manage user permissions, troubleshoot issues, and coordinate shared computing resources to support the team’s model training and experiments.

AI-assisted Research & Development

Claude CodeCodexAgent Skills

I use AI coding tools for research development and experimental iteration, and develop open-source Agent Skills for paper reading, research idea discovery, and verification. This practice involves research task decomposition, workflow design, and evidence checking.

Explore academic-skills on GitHub ↗

Contact

Open to discussions and collaborations across multimodal learning, reliable AI, medical AI, and emerging embodied AI.

I am currently seeking PhD opportunities for Fall 2027. My interests include VLMs, cross-modal alignment, visual-language grounding and evidence reasoning; domain generalization, distribution shifts, test-time adaptation and robustness; medical imaging and computational pathology; and frontier developments in AI, including VLA, world models, and 3D reconstruction.